How I'm Building Tourist: A Cloud Coding Agent That Lives in a City
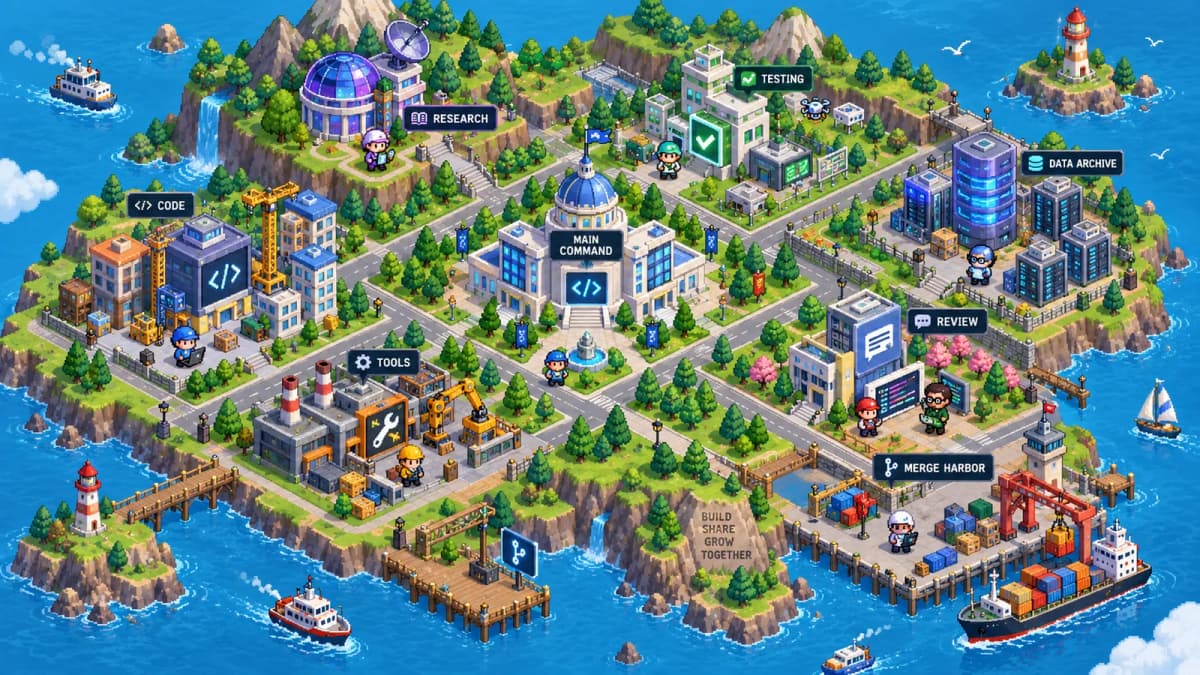
Tourist loads a repository as a city, one building per file, and runs coding agents against it. Scoring, memory, and a reinforcement-learning policy sit on the same run. A real pull request is stage 8.
 Harsh Sinha
Most coding agents still behave like a very smart intern who forgets the office every morning.
You describe a bug. The agent searches, finds auth.ts, patches it, runs tests, and opens a pull request. Tomorrow you describe a related bug. It searches the same folders, rereads the same README, retries the approach that already failed on Tuesday, and dumps half the repo into the prompt “just in case.”
The model is not the bottleneck anymore. The session is.
Tourist is that office, drawn as a city and staffed like a small engineering team. The goal is one system, not a chat window with a map taped on:
A repository becomes an island. Each file is a building.
Agents read, edit, test, and review on that tree.
Every finished run gets a score.
Memory keeps what the score says was worth keeping.
A reinforcement-learning policy later prefers the choices that scored well.
GitHub is where the work leaves as a pull request.
The city is the part you can open. Paste a public GitHub URL and Tourist fetches that default branch, drops images and generated assets, and lays the remaining files out as buildings. Folders become sectors. Tests, tools, review, and the harbor are landmarks, not files. The same generator draws Tourist’s own repo. That viewer is deployed.
The agents, the score, and a first memory file are in the repository behind it. A coder, a coder–tester–reviewer chain, and an opt-in swarm can edit a checkout, run node --test, and commit locally. The cloud API can run that same runtime in a Daytona sandbox and return a patch. reward_v1 is written on the run. Notes live in a JSON file and come back by keyword overlap. The policy that would learn from those scores is specified, and it is not allowed to change behavior yet. A real pull request is stage 8. create_pull_request records the call.
checkpoints.md is the build order. Where it disagrees with the older plan.md, the board wins. The old plan wanted a real pull request before a swarm or a tool builder. The repo built the agent on a local checkout first, and left GitHub for last.
The six layers
The user flow I want is still boring on purpose. Connect GitHub, bring a key, describe a task, wait. Under that loop the product is six layers. The table is the goal and the code, side by side.
| Layer | Goal | In the repo now |
|---|---|---|
| City | The repository is an island. Each file is a building. Tests, tools, review, and pull requests are landmarks. | A public GitHub URL renders that default branch. 68 file-type buildings. Builders wait at town hall. |
| Agents | A supervisor picks one coder, a specialist chain, or a swarm. They edit, test, and review in a sandbox. | solo_coder, coder–tester–reviewer, and an opt-in swarm. CLI, plus a Daytona API that returns a patch. |
| Scoring | Every finished run stores reward_v1: tests, diff, tokens, latency, and later the pull request, CI, merge, and revert. | heuristic_v1 writes completed, tests, diff, tokens, and latency. Pull-request scores are not filled in. |
| Memory | User, codebase, and episodic notes, plus code rules, retrieved as a small pack. Global memory stays inactive until it is promoted. | JSON file, keyword overlap, at most 8 notes. The agent memory tools answer that stage 6 is not available. |
| Reinforcement learning | Learn discrete choices — model, topology, context, tools, memory, stop, tests — from those scores. Do not train the model that writes the code. | The decision table and shadow → canary → active rule are specified. No policy is promoted. |
| GitHub delivery | A GitHub App pushes the task branch and opens a pull request. The harbor shows that pull request. | create_pull_request records the call. Nothing pushes. |
The public site at the Tourist city shows the first layer. You can paste owner/repo and walk the island. The page still marks “give it work” and the memory section as coming soon, because those layers are not started from that prompt. They are started from the tourist CLI and the cloud API. A visitor can paste a run id and a viewer token into the terminal panel if a cloud run already exists.
What I am not building, at least not first:
- a new foundation model
- online PPO against the model that writes the code
- Kubernetes as a personality trait
- a custom sandbox runtime
- a 40-agent swarm that starts because the prompt was long
- a VS Code clone
- a claim that the city is alive because the cars move
If I confuse those, I will spend the next month making ships prettier while create_pull_request is still a notebook entry.
The city loads the repository
This is the layer that runs in the browser. I care about it more than a dashboard, and the pull request is still what has to leave the island.
Software is spatial whether we admit it or not. You already say “the auth area,” “the payments module,” “the messy legacy folder.” Mapping that to an island is not a gimmick if the mapping is generated from the repo tree, not hand-authored.
| Software | City object |
|---|---|
| Repository | Island / city |
| Major folder | Sector |
| Subdirectory | District |
| File | Building |
| Agent | Character |
| Tool creation | Workshop |
| Tests | Testing facility |
| GitHub / PRs | Harbor |
Paste owner/repo on the landing page, or open /owner/repo. The page calls the public GitHub API with no user token, asks the world generator for a CitySnapshot, and renders it. The same generator serves the local island. Images and generated assets stay off the map. The import keeps at most 400 files. Line counts are not read from the files. They are a hash of the path: 24 plus that hash modulo 420. Building height on an imported city is a costume.
The viewer is isometric SVG and DOM. React Three Fiber is still a possible later renderer. It is not this one. The catalog has 68 building designs, including a generic fallback and a testing building so *.test.ts does not have to look like an ordinary TypeScript file. Equivalent extensions share a design. .yml and .yaml are the same building.
Landmarks in the protocol are the command center, testing facility, data archive, tool workshop, research lab, review center, and merge harbor. On the island you meet them as town hall, the test facility, the skill harbor, the review navy, and the airbase where a repository arrives. Cars follow the street grid. Ships loop the water and pause at the harbor. Clouds take curved routes. That motion is atmosphere. The code comment in the canvas is explicit: snapshot states are historical report evidence, and builders leave town hall only when a caller passes live edit ids. The public city page does not pass them. The crew stands in the plaza. The operations modal’s pull-request list is empty, with the copy “No pull requests are connected to this snapshot yet.”
Private repositories wait for stage 8, when an installation token exists. Storing a city so it can be reopened by id, and replacing the hashed line count with a real one, are deferred city work. They are not the next AI stage.
A file diff is supposed to anchor to a building. Tests anchor to the testing facility. A pull request anchors to the harbor. Failures put a warning on a district. The fixture report route still has file, test, and pull-request anchors. A GitHub import’s report section points at the island and says the tree was mapped. It does not describe a run, because there was no run.
If stage 8 regresses, or never arrives, city polish pauses. A beautiful empty harbor is a trailer. A shareable report whose snapshot matches a real run is a product.
The problem I am actually trying to solve
Coding agents got good fast. They can search a repo, edit files, run tests, and open PRs. What is still weak is everything around the session:
- they rediscover the same architecture every time
- they forget the approach that already failed last Tuesday
- they preload too much context, then drown in it
- they have a fixed toolbelt
- they do not systematically get better from merged PRs, reverted PRs, flaky tests, or “please don’t do it that way”
- when they work in the cloud, you get a log stream, not a place you can look at
I have already written about two pieces of this: memory as a coordination layer, and agents that know when to stop. Tourist is where those constraints have to survive contact with a repository.
Cursor’s writing on this is still the clearest outside reference. In Dynamic context discovery, the argument is that as models get better as agents, you should give them fewer details up front and make it cheap to pull the rest. Static context versus dynamic context discovery. The claim is not just “saves tokens.” Keeping contradictory or irrelevant material out of the window can improve the answer (Katz, 2026).
That is still the architectural tenet:
Huge available context. Tiny active context.
The rest of Tourist is what happens if you take that seriously, then add persistence, GitHub-native delivery, and a city as the reporting surface. The tenet is ahead of the code. Today’s agent searches with ripgrep and receives a memory pack of at most eight notes. The retrieval ladder below is the design it is supposed to grow into.
The sequence changed
The failure mode for a project like this is obvious. Memory, multi-agent, tool factories, reinforcement learning, and a 3D world are five startups. The first plan put a quality gate in front of that: no swarm, no tool builder, no “live city” claim, until one agent could open a real pull request.
The checkpoint board reversed the early order, on purpose. It says that where it disagrees with plan.md, follow the board. Stages 1 through 7 do not connect a GitHub account. Repository work happens on a local fixture or a sandbox clone. GitHub tool names exist so the agent can call them. The adapter records the call.
| Stage | Exit | Status |
|---|---|---|
| 0 · Village | A public GitHub URL opens a city of that default branch | Checked. Landing page, /owner/repo, and the local report route |
| 1 · Tools | A test script edits a fixture, runs tests, commits, and records a fake PR | Checked. Registry, allowlisted shell, recording GitHub adapter |
| 2 · Agent | One agent produces a tested local commit and a tool trace | Checked. Live OpenAI fixture runs recorded; other providers contract-tested |
| 3 · Sub-agents | Coder, tester, and reviewer run in order, with one review return | Checked on fixtures. Research exists as a role and is not in the default chain |
| 4 · Swarm | Two independent edits finish as one tested branch | Checked on local worktrees. Opt-in, 2–4 disjoint file sets |
| 5 · One runtime | The same entry point can run solo or swarm, and can register one run-scoped tool | Checked on fixtures. build_tool is count_lines only |
| 6 · Memory | A second task reuses a stored note, and the log shows that id | Unchecked. JSON keyword store is a precursor, not this exit |
| 7 · Policy | A promoted policy beats the heuristic on an eval, at equal or lower cost | Unchecked. reward_v1 is logged. Promotion is not built |
| 8 · GitHub | A connected repo and an issue come back as a real pull request | Unchecked. create_pull_request records the call. Nothing pushes |
The reason for the flip is practical. You cannot reconstruct a faithful tool trace later, and you cannot tell whether a topology was a good idea if the only thing you ever ran was a happy-path coder. So the board builds the agent on a checkout first: tools without a model, then one coder, then specialists, then a swarm that is hard to start by accident, then one entry point. Memory that other tasks can reuse comes after that architecture holds. A policy is allowed to change behavior only after an eval. GitHub is the last adapter to go live, because a push is the first action that leaves the machine.
The risk is the one the old gate was designed to prevent. A swarm that has never opened a pull request can become the product. I am keeping the fear and moving the control: city polish and topology experiments do not get to count as shipping until stage 8’s exit is checked. That exit is specific. A connected repo and an issue go through the stage 5 runtime and come back as a real pull request, and the same trajectory’s reward updates from that pull request.
The agents
The runtime is TypeScript, behind our own interfaces, using the AI SDK tool loop. The older docs still describe a Python process and the OpenAI Agents SDK. That is not what packages/agent-runtime is.
A task carries a model id and a key. The catalog is explicit: unknown ids fail before any provider request. The default is gpt-6-sol. OpenAI, Anthropic, and Gemini models are in the table, with reasoning levels where the provider supports them. The key is passed into the run. It is not written into the trajectory, and it is not handed to a tool. The board records bounded live OpenAI runs, in solo.live.test.ts and team.live.test.ts, that each produced a passing fixture commit. Anthropic and Gemini routing is contract-tested. Those paths were not live-tested without keys.
Topology is a function, not a model acting as a manager. If the caller passes two to four disjoint file assignments, the run is a swarm. Otherwise a task that mentions a bug, a fix, a race, a regression, auth, security, or a refactor — or any task longer than 120 characters — takes the team path. Everything else is one coder. The “supervisor” in the design notes is real as a role with no file-editing tools. The choice it is supposed to make is, today, that heuristic.
| Topology | When it runs | Who works |
|---|---|---|
| solo_coder | No swarm parts, and the task is short and does not match the bug keywords | One coder. The runtime then tests, commits, and records a pull request |
| coder_tester_reviewer | Task longer than 120 characters, or it mentions bug, fix, race, regression, auth, security, or refactor | Coder, tester, reviewer. One CHANGES_REQUIRED loop. Review must start with ACCEPT |
| swarm | Caller passes 2–4 disjoint file assignments | One worktree per coder, then one integration branch and tests |
The coder may only act through the registry. Search is ripgrep with a fixed string, at most 20 matches per file, and the tool returns at most 50,000 characters. read_file refuses a file above 200,000 characters. Shell is an allowlist: node --test, or pnpm / npm with test, typecheck, or build. There is no arbitrary shell string, and the git tools cannot push.
On a local coding run the checkout has to be clean. The runtime creates tourist/task-…, lets the agent edit, runs node --test with a 120 second limit, commits, and then calls create_pull_request. That call appends a recorded flag to the run. GitHub is never contacted. Plan and ask modes get read_file, search, git_status, and git_diff, capped at 12 model steps. Debug mode wraps the task as “reproduce, find the cause, fix, add a regression test,” then uses the coding path.
The team path is coder, then tester, then reviewer. The reviewer’s last message has to start with ACCEPT. CHANGES_REQUIRED sends the coder and tester around once. A second rejection fails the run. The research role exists, with read and search only. The default chain does not call it.
The swarm path is the one I am most careful about. Each coder gets a Git worktree and a write allowlist of its own files. An integration step merges those branches onto one task branch and runs tests. A failed test or a merge conflict goes back to the owner once, if the failure names that owner. If ownership is ambiguous, the run stops. The worktrees are removed afterwards.
Events from these runs already use the names the city was given: agent.spawned, file.changed, tool.called, test.passed, test.failed. They feed the CLI and the cloud event log. They do not yet move a pawn on the island.
The tool builder is one operation
Stage 5 includes a tool builder, and it is deliberately small.
The solo coder can call build_tool. The manifest is Zod-checked. The id has to look like local_something. The only legal operation is count_lines. The caller supplies one to five fixtures, path plus expected line count. The implementation is a read of a file through the same path check as read_file, not generated JavaScript and not a shell. If a fixture disagrees, the tool is not registered. If it passes, the next model phase on that same run can call it. The registry forgets it when the process ends. It is not a global skill.
That is the whole factory. A workshop that can invent arbitrary programs is a later product, and it stays behind the stage 5 constraint until a run can show that a reused tool improved the reward. Right now the interesting question is whether the agent even reaches for a line counter when the manifest is this strict. The tests show the registration path. They do not show that a model wanted the tool.
The cloud path returns a patch
apps/api accepts a public owner/repo, a task, a mode, a model id, and an optional swarm assignment. The request also carries the provider key in a header. The key sits in the in-memory queue, goes into the sandbox environment, and is not written on the run record.
The executor talks to Daytona. It creates a TypeScript sandbox, clones the public repository at depth 1, uploads a worker bundle and the task JSON, and runs the worker for up to 900 seconds. Tool and stage events are polled from a file inside the sandbox. On the way out, the API reads a result JSON — refused above 5 MB — keeps the patch, and deletes the sandbox.
The queue is one process. It runs one job at a time and will hold ten waiting runs. Restart the API and unfinished runs are marked failed. A succeeded coding run stores reward_v1 with the token counts from the model response, the latency, whether a patch exists, and testsPassed: true, because a failed test throws before success is recorded. A failed cloud run stores completed: false and zero tokens. Those zeros are a placeholder, not a measurement of the failed attempt.
So the laptop-closed story is half true in code. The sandbox can outlive the request that started it, inside that 900 second command. The API does not push, does not open a pull request, and does not keep the machine. The checkpoint board says a real Daytona execution had not been run when the board was reviewed. Unit tests cover the server, the queue, and the executor’s contract. I am not going to describe a cloud run I cannot point at in that record.
The CLI is the same runtime with a terminal in front of it. tourist can plan, ask, debug, or run against a local checkout, or send the task to TOURIST_CLOUD_URL when that is set. The interactive prompt has a command ribbon and a model picker with the price table. Coding still requires a clean checkout, which is an awkward way to protect work you have not committed, and the right one until the sandbox is the default.
Local execution is not an operating-system sandbox. The instruction in the runtime README is to use a disposable checkout. That constraint stays until Daytona, or something like it, is the path a normal run takes.
| Limit | What the code does |
|---|---|
| Search | ripgrep, fixed string, 20 matches per file, 50,000 characters returned |
| Read and write | UTF-8 files inside the checkout. read_file refuses a file above 200,000 characters |
| Shell and tests | node --test, or pnpm/npm test, typecheck, or build. Test tool limit is 120 seconds |
| GitHub tools | list_issues, get_issue, and create_pull_request append the call. They do not use the network |
| Tool builder | count_lines only, 1–5 fixtures must pass, forgotten when the process ends |
| Memory pack | Keyword overlap, at most 8 notes, 1,000 characters each in the prompt |
| Cloud run | Public repo, shallow clone, Daytona sandbox, patch returned, sandbox deleted. Queue is serial, 10 waiting |
| GitHub import | Default branch, at most 400 files. Line count is 24 plus a hash of the path, modulo 420 |
Context: the design is still discovery, the code is still a checkout
This is the part I am most sure about, and the part the implementation has barely touched.
Older agent setups stuffed the prompt with the repo tree, semantic matches, memories, tool catalogs, and chat history “just in case.” Cursor’s direction is the opposite. Agents start with lightweight facts and discover the rest through tools (Katz, 2026; Cursor).
The teaching version of that contrast looks like this. These are not Tourist measurements. They are a sketch of why “just in case” is expensive:
Loading chart… Data is available below.
View chart data
| strategy | Repo status / tree ( tokens) | Retrieved code ( tokens) | Memories ( tokens) | Tool schemas ( tokens) | History / summaries ( tokens) |
|---|---|---|---|---|---|
| Static dump | 12000 | 8000 | 5000 | 14000 | 9000 |
| Dynamic discovery | 300 | 3500 | 800 | 900 | 4500 |
Search is hybrid in the design, and ripgrep in the code
Cursor reports that semantic search improved coding-agent question accuracy by 12.5% on average (range 6.5%–23.5% depending on the model), that grep and semantic search together currently perform best, and that the benefit is larger on big codebases. Their A/B tests also showed higher code retention on large repos when semantic search was available (Heule, Jia & Jain, 2025).
Loading chart… Data is available below.
View chart data
| model | Question accuracy lift (%) |
|---|---|
| Lowest model in Cursor's set | 6.5 |
| Average across models | 12.5 |
| Highest model in Cursor's set | 23.5 |
| Metric | Reported change | Caveat |
|---|---|---|
| Code retention, all agent queries | +0.3% with semantic search | Many queries do not need search |
| Code retention, repos with 1,000+ files | +2.6% with semantic search | Larger effect on large codebases |
| Dissatisfied follow-up requests | +2.2% when semantic search was removed | Measured across all agent queries |
The retrieval ladder I still want:
symbol lookup → ripgrep → LSP → semantic search → memory
Tourist has the second step. embed_codebase is registered and returns “Available in Stage 6.” There is no tree-sitter index, no language server, and no vector store in the running system. plan.md still names Qdrant. The checkpoint board says the embedding engine is chosen later. I am leaving that choice open until stage 6 has a record store worth indexing.
Cursor’s Dropbox writeup is a useful existence proof that indexing hundreds of thousands of files is a product problem, not a prompt problem (Cursor). A Tourist import currently keeps 400 files and estimates their size. We are not at that problem yet. We should not pretend the city of a large repo is the same as an index of it.
Long tool output is still in the model’s hands
npm test can be 40,000 tokens. Truncating it loses the assertion you needed. Cursor writes long tool responses to files and lets the agent read slices. They say this reduced unnecessary summarization (Katz, 2026).
The trace Tourist stores is redacted: stdout, stderr, and file contents become a character count. The model receives the full tool result. Search is capped. A test log is not. The sandbox contract I still want is an artifact plus a tail:
{
  "exit_code": 1,
  "artifact": "test-output.log",
  "tail": "...AssertionError..."
}
Maybe 300 tokens. Then a line slice only if the agent asks. That is not built. It matters more once the test command is a real project’s suite and not node --test on a fixture.
Tools should be discovered, not preloaded
This matters more once agents can create tools that are worth keeping.
Cursor’s MCP finding: loading every tool description is expensive; syncing descriptions to files and letting the agent look them up cut total agent tokens by 46.9% on runs that actually called an MCP tool (Katz, 2026). They also adopted the Agent Skills open standard: a name and a description can sit in static context, and the full instructions are pulled when relevant (Anthropic).
Loading chart… Data is available below.
View chart data
| setup | Relative total agent tokens |
|---|---|
| MCP tools always loaded | 100 |
| Tool descriptions as files | 53.1 |
The registry can already hand a caller a subset by id. The team path uses that: a reviewer does not get write_file. What we do not have is retrieval over a large catalog. The solo coder’s list is short enough that dumping it is fine. It will not stay fine if stage 5’s one-line-counter grows into a real workshop.
The extra step: context selection is part of the policy
Cursor trains retrieval from agent traces: look at what the agent eventually opened, ask what should have been retrieved earlier, train embeddings toward that (Heule, Jia & Jain, 2025).
I want that loop as a discrete, logged decision, not only as a better embedding model.
Every run is supposed to choose a context_budget (4k / 8k / 16k), a tool_pack, and a memory_pack. Those choices go into the trajectory. Later, contextual bandits can prefer packs that helped. That decision table is stage 7. The field written today is smaller: heuristic_v1, the mode, and the topology the keyword rule picked.
A useful scoring rule for the router, still a design:
context_score
= (relevance × expected usefulness × confidence) / token_cost
If auth.ts is 1,800 tokens at 0.98 relevance and README.md is 7,000 tokens at 0.31, the README does not get to eat the window.
| File | Tokens | Relevance | Expected usefulness | Confidence | Score × 1,000,000 |
|---|---|---|---|---|---|
| auth.ts | 1,800 | 0.98 | 0.90 | 0.85 | 416.5 |
| session.ts | 2,400 | 0.71 | 0.62 | 0.80 | 146.7 |
| README.md | 7,000 | 0.31 | 0.40 | 0.60 | 10.6 |
Loading chart… Data is available below.
View chart data
| file | Illustrative context score |
|---|---|
| auth.ts | 416.5 |
| session.ts | 146.7 |
| README.md | 10.6 |
The goal is not maximum context. It is minimum sufficient context.
Memory: a JSON file now, a promotion pipeline later
Memory is how the system stops being session-oriented. It is also how you leak a secret into the next prompt if you are sloppy.
What runs is MemoryStore, a JSON file. The CLI uses ~/.tourist/memory.json unless TOURIST_MEMORY_FILE is set. Notes have a scope of user, codebase, or episodic, a repo id when they are not user-scoped, and a body of at most 2,000 characters. Retrieval is keyword overlap: words of three characters or more, user notes always eligible, others only if they share a word with the task, then at most eight notes. The cloud API loads its own file, mixes those hits with notes the CLI sent, and on a succeeded run that produced a patch writes one episodic line: “Completed” plus the first 300 characters of the task.
The agent’s own tools, read_memory, write_memory, delete_memory, return “Available in Stage 6.” The pack is injected by the CLI or the API before the model starts. The coder does not query it.
Stage 6 is the version I am willing to call memory. Postgres is the record store. An embedding index, engine still unchosen, holds vectors for those records and for code chunks. read_code_rules runs before the first edit and loads AGENTS.md, CLAUDE.md, .cursor/rules/**, a user taste file, and saved code_rule memories. A file wins when it disagrees with a memory. The reviewer checks the diff against the pack that was loaded. Global rows may be logged as candidates. Nothing with scope=global and status=active is readable. Agents do not promote their own notes.
| Scope | Holds | Write rule |
|---|---|---|
| User | Preferences such as TypeScript, smaller PRs, pnpm | User- or workspace-scoped; never promoted globally |
| Codebase | Architecture, conventions, fragile areas, past agent work on this repo | Repo-scoped; versioned with the tree |
| Episodic | This task failed because X, then Y worked | Task-scoped; retrievable, not always in the prompt |
| Procedural / tool | For this class of problem, use that tool | Candidate until replayed |
| Shared task | Scratch space for later multi-agent runs | Exists in the schema; unused until Gate C |
| Global | Reusable patterns across repos | Default deny. Agents never write scope=global, status=active |
The pipeline I still want, once that store exists:
default deny
→ sanitize
→ candidate
→ multi-repo promote
→ budgeted retrieve
→ demote
Keyword overlap will happily retrieve “use pnpm” for a task about pnpm, and it will also retrieve it for a task that happens to contain the word “use.” That is a fine precursor. It is a bad thing to call codebase understanding.
Scoring: reward_v1 on every finished run
The score is its own layer. It is not the reinforcement learner. It is the record the learner is allowed to read later.
A finished run stores two objects. policy says which rule produced the run. Today that version is heuristic_v1, plus the mode (run, plan, ask, or debug) and the topology when the run has one. reward_v1 stores:
completed
testsPassed
diffProduced
inputTokens
outputTokens
latencyMs
On a coding run that returns, testsPassed is true because a failed node --test throws before the runtime records success. diffProduced is true when a local commit or a cloud patch exists. Token counts come from the model response. Latency is the wall clock of that request.
The score is supposed to grow, not get invented. Stage 7 adds tool reuse, and retrieval credit for a memory that was in the prompt on a successful run. Stage 8 adds the delayed signals on the same object: pull request opened, CI finished, merged, reverted. Those fields are absent on purpose. A missing pull-request score is not a zero, and it is not a guess.
A failed cloud run is the hole in the log. It stores completed: false and zero tokens. The zeros are a placeholder. They should be fixed before any policy is trained on the file.
Reinforcement learning: discrete choices, not a new model
I am going to stay strict about language. Tourist does structured policy learning over trajectories. It does not train the model that writes the code.
The non-negotiables:
- Do not train foundation-model weights in this version.
- Do not do online PPO against the main model.
- Every completed run should write a trajectory and a reward. Incomplete learning records are bugs.
- Only discrete, versioned decisions are learned.
- No policy promotion without an eval gate. Logging is not learning.
- Global memory graduates under rules.
The action space is small on purpose. The supervisor may pick a model class, a topology, a context budget, a tool pack, a memory pack, a stop policy, and a test policy. A new decision key needs a protocol change, a default, logging, and an eval. The context the bandit sees is the task: type, repo size, languages, whether CI exists, what failed last time. Li et al.’s LinUCB work is the usual citation for learning that choice without training the underlying model (Li et al., 2010).
| Decision | Example arms |
|---|---|
| model | fast / coding / reasoning |
| topology | solo_coder / coder_tester / … |
| context_budget | 4k / 8k / 16k |
| tool_pack | retrieved tool ids |
| memory_pack | retrieved memory ids |
| stop_policy | stop_on_green / max_3_retries / ask human |
| test_policy | unit_only / unit+lint / full CI |
Policies go shadow, then canary, then active. A shadow policy scores runs without changing what the live path does. Promotion requires the eval to be at least as successful as the current default, at equal or lower cost. Rollback restores the previous version and keeps the trajectories. None of that machinery is in the repo. The eval set of fixture tasks is not either.
SWE-bench exists so nobody has to pretend vibes are a metric (Jimenez et al., 2024). I will still need a fixture-repo eval of our own, because Tourist’s loop includes a sandbox, a city, and eventually GitHub, not just a patch. SWE-agent is the supporting argument for spending time on the interface: the agent–computer boundary changes success rates (Yang et al., 2024). An allowlisted shell and a recorded pull request are already that kind of interface. They are a small one.
The live path does not consult this table. Topology is the keyword rule in the agent section. The model is whichever id the user picked. Stage 7 is the exit where a promoted policy beats that heuristic on success rate, or on cost at the same success rate, and every run still has a complete trajectory plus reward_v1.
The stack, as it is and as it was written down
I wanted to spend engineering time on agent quality, context, memory, and the city. The current code follows that more closely than the original service map did. It also leaves a documentation drift: README.md and plan.md still describe Python, OpenAI-only keys, Qdrant, and a Three.js world. The running tree is smaller.
| Layer | Choice | Why |
|---|---|---|
| City viewer (running) | Next.js, React, TypeScript, isometric SVG/DOM | Public repo to CitySnapshot, 68 file-type buildings, inspection, ambient traffic |
| Agent runtime (running) | TypeScript + Vercel AI SDK + Zod | Provider-neutral tool loop. The older plan's Python and OpenAI Agents SDK are not this package |
| Models (running) | OpenAI, Anthropic, and Gemini, task-scoped keys | Explicit catalog, default gpt-6-sol. Live fixture evidence recorded for OpenAI |
| CLI (running) | tourist-agent-cli | Same runtime locally or against the cloud API. Ribbon, model picker, modes |
| Cloud API (coded) | Node HTTP server + Daytona SDK | Public clone, disposable sandbox, patch returned, sandbox deleted. A live Daytona run was not recorded on the board |
| Memory (precursor) | JSON file, keyword overlap | User, codebase, and episodic notes. Postgres and an embedding index are stage 6 |
| Rewards (precursor) | heuristic_v1 | Logged on finished runs. Shadow, canary, and active promotion are stage 7 |
| GitHub delivery (stage 8) | GitHub App | Today the tools record the call. Push and a real pull request are the last stage |
| Vectors (stage 6) | Unchosen | plan.md still names Qdrant. The checkpoint board picks the engine when the record store exists |
| 3D world (possible later) | React Three Fiber + Three.js | Not the current renderer. The working viewer is isometric SVG and DOM |
The monorepo that exists:
tourist/
├── apps/web                  # city, landing page, run viewer
├── apps/api                  # cloud queue, Daytona executor, run store
├── packages/agent-runtime    # tools, topologies, models, JSON memory
├── packages/cli              # tourist terminal, local and cloud
├── packages/protocol         # CitySnapshot, PublicReport, world schema
├── packages/world-generator  # file list → deterministic layout
├── checkpoints.md            # build order
├── plan.md                   # older gate write-up
└── prd.md                    # design reference
There is no separate Python service, no worker app, and no package whose only job is GitHub. The sandbox worker is a bundle the API uploads. Schema changes still belong in packages/protocol in the same change as the viewer. If the city and the agent disagree about what a building is, that is a protocol bug.
Daytona stays the sandbox I want for the laptop-closed path. OpenAI’s sandbox-agent model is the shape: the agent still has instructions, tools, and guardrails, and the execution boundary is a machine that owns the files (OpenAI Developers). The TypeScript SDK is what the API imports. Pause-on-exit is not what we do. We delete the sandbox in a finally block. That is the right default until a run is long enough to be worth resuming, and it means “close the laptop” currently means “the request already handed the work to Daytona,” not “the workspace will be there tomorrow.”
Keys are a product constraint. The user’s provider key runs the agent. I do not want to become a model reseller in order to finish stage 8. The price table in the CLI is an estimate from provider docs checked on 29 September 2026, and the runtime README says to re-check it before anyone uses it for billing.
What has to happen before I call this a cloud agent
Stage 6, then 7, then 8. The board says not to start a stage until the previous exit is checked. Stage 5’s exit is checked on local fixtures: one entry point completes a small task with one agent and a larger task with a swarm, and both runs can be inspected from the trajectory and the event list. The next exit is a second task that reuses a stored codebase or episodic note, with the run log showing which note was used.
After that, stage 7’s exit is an eval where a promoted policy beats the starting heuristic on success rate, or on cost at the same success rate, and every run still has a complete trajectory plus reward_v1.
Stage 8 is the GitHub App. Permissions stay limited to the repositories the user selects. The browser starts the install. The server stores the installation id and mints a short-lived token. The token never enters the city snapshot, the trajectory, or the page. The same tool ids gain a live implementation: list issues, read an issue, list pull requests, open a pull request from the task branch, read checks. Push is allowed only for the task branch, only after the local commit. Private cities use the installation token. Anonymous public URLs keep using the public API.
The original first month was a different calendar: city schema in week one, a fixture city in week two, report anchors in week three, a real run minting a report in week four. The city half of that month happened, and then kept going. The agent half happened on a checkout, without the pull request. I am leaving the old week table out of this update so it does not keep reading like a promise.
| Fear | Control |
|---|---|
| Six products at once | checkpoints.md is the order. Stage 6 before 7 before 8. plan.md loses when they disagree |
| Vague 'RL' | heuristic_v1 is a log. Promotion needs an eval. No PPO against the model that writes the code |
| Global memory as a secret-shaped junk drawer | The JSON store has no global scope. Stage 6 keeps global rows inactive |
| A swarm that has never opened a pull request | Swarm is opt-in on fixtures. It does not count as shipping until stage 8’s real PR exit |
| City polish replacing the harbor | Ambient traffic stays atmosphere. Builders move only for live edit ids, which the public page does not send |
| A tool factory that emits shell scripts | build_tool is count_lines, fixtures must pass, and the tool dies with the run |
Where that leaves the bet
Cursor is iterating on the harness in public. OpenAI is standardizing sandbox agents and skills. The open space I want is a cloud loop that remembers, learns discrete policies from outcomes, and makes the work visible as a city you can share.
A log stream tells you the agent did something. A city tells you where. The city can already tell you where a public repository’s files are. It cannot yet tell you where an agent went, because the agent’s events stop at the log, and the harbor has no pull requests to receive.
The next time a cloud agent opens a pull request while your laptop is closed, the interesting question is not only whether the patch is right.
It is what the system remembered from last Tuesday, what it refused to load into the window, and whether you can point at a building and see the work. Tourist can draw the building. The memory, the refusal, and the pull request are the next three stages, in that order.
Sources and further reading16 references
- Dynamic context discoveryJediah Katz, Cursor Blog, 6 Jan 2026
Static vs dynamic context; long tool outputs as files; chat history as files after summarization; Agent Skills; MCP tool descriptions as files; 46.9% fewer total agent tokens on MCP-calling runs; terminals as files.
- Continually improving our agent harnessCursor
Less static preload; agents start light and discover.
- Improving agent with semantic searchStefan Heule, Emily Jia & Naman Jain, Cursor Blog, 6 Nov 2025
+12.5% average question accuracy with semantic search (range 6.5%–23.5%); grep + semantic together best; trace-trained embeddings; code retention and follow-up A/B results.
- Dropbox uses Cursor to index over 550,000 filesCursor
Indexing at scale is a product problem. The model does not eat the whole corpus.
- The next evolution of the Agents SDKOpenAI
Earlier architecture note: harness, sandbox execution, skills. The running Tourist runtime uses the Vercel AI SDK, not this Python SDK.
- AI SDK: tools and tool callingVercel
The provider-neutral tool loop in packages/agent-runtime. OpenAI, Anthropic, and Gemini adapters sit behind Tourist's own model catalog.
- Tourist checkpointsHarsh Sinha, tourist repository, last reviewed 29 Sep 2026
Build order. Stages 0–5 checked. Stages 6–8 unchecked. Where this file disagrees with plan.md, the repository says to follow this file.
- Sandbox agentsOpenAI Developers
The execution boundary is the sandbox. Tourist's API creates a Daytona sandbox, returns a patch, and deletes the machine.
- Using the OpenAI Agents SDK with Daytona SandboxesDaytona
Documented Agents SDK path with pause-on-exit. Tourist's executor uses the TypeScript SDK and deletes the sandbox instead of pausing it.
- Equipping agents for the real world with Agent SkillsAnthropic
Skills as files with a name and description; load full instructions on demand.
- A Contextual-Bandit Approach to Personalized News Article RecommendationLi, Chu, Langford, Schapire, WWW 2010
LinUCB: discrete arms plus context, without training the underlying model.
- SWE-bench: Can Language Models Resolve Real-World GitHub Issues?Jimenez et al., ICLR 2024
Opening a PR is not enough. Held-out eval still matters.
- SWE-agent: Agent-Computer Interfaces Enable Automated Software EngineeringYang et al., NeurIPS 2024
Interface and harness design change agent success, not only the base model.
- React Three Fiber documentationPoimandres
A possible later renderer. The working city is isometric SVG and DOM, with 68 catalogued building sprites.
- GitHub Apps documentationGitHub
Stage 8 plan: installation, limited permissions, short-lived tokens. The current tools record the call and do not contact GitHub.
- Model Context ProtocolAnthropic / MCP
Why tool catalogs explode; background for Cursor's MCP token result.